Author Archives: kevin

About kevin

I write the posts

Profile Anything in Any Language in Under a Minute

Want to know how to get rough profiling of any tool written in any language, whether you control the source or not? Keep reading.

For example, here's the output you get when you compile Go from source code. Each of these lines prints out a few seconds apart. How would you go about getting timings for each individual step, or how would you notice if one step was suddenly executing much more slowly than it did three days ago?

$ GOROOT_BOOTSTRAP=~/go1.10 ./make.bash
Building Go cmd/dist using /Users/kevin/go1.10.
Building Go toolchain1 using /Users/kevin/go1.10.
Building Go bootstrap cmd/go (go_bootstrap) using Go toolchain1.
Building Go toolchain2 using go_bootstrap and Go toolchain1.
Building Go toolchain3 using go_bootstrap and Go toolchain2.
Building packages and commands for darwin/amd64.
---
Installed Go for darwin/amd64 in /Users/kevin/go
Installed commands in /Users/kevin/go/bin

There are a few different methods you can use to get a sense for this, but I wanted to share my favorite one. Don't reach for a profiler, don't try to set a global variable, or do start/stop timing in code. Don't even start figuring out how to configure a logger to print timestamps, and use a log output format.

Then when you've done all this, rerun the command and pass it through a command that attaches timestamps to every output line. For example, I have a tool called tss (based on ts in the moreutils package) that does this. Pipe your command to tss and you'll get output like this:

$ GOROOT_BOOTSTRAP=~/go1.10 ./make.bash | tss
     11ms         Building Go cmd/dist using /Users/kevin/go1.10.
    690ms   679ms Building Go toolchain1 using /Users/kevin/go1.10.
  11.435s 10.745s Building Go bootstrap cmd/go (go_bootstrap) using Go toolchain1.
  18.483s  7.048s Building Go toolchain2 using go_bootstrap and Go toolchain1.
  40.788s 22.305s Building Go toolchain3 using go_bootstrap and Go toolchain2.
 1m0.112s 19.324s Building packages and commands for darwin/amd64.
1m19.053s 18.942s ---
1m19.053s      0s Installed Go for darwin/amd64 in /Users/kevin/go
1m19.053s      0s Installed commands in /Users/kevin/go/bin

The first column is the amount of time that has elapsed since the tool was invoked. The second column is the amount of time that has elapsed since the previous line was printed.

The good thing about this technique is you can use it in pretty much any situation - you don't have to know anything about the code besides:

  • how to invoke it
  • a rough idea of which code paths get hit
  • how to print things to stdout

Just start adding print lines around interesting bits of code.

For example, you might have this in your test suite in Ruby to empty the database. How much time does this add to every test in your suite? Put print lines before and after to find out.

config.after(:each) do
  puts "database clean start"
  DatabaseCleaner.clean
  puts "database clean end"
end

Similarly, if you wanted to find out why it takes so long for your test suite to start running or your web framework to boot, you can annotate your spec_helper or bootstrap file, the top of the test file, before and after require lines, and the start and end of the first test in the suite. You can even drill down into third party libraries, just find the source file on disk and start adding print statements.

You can also use it with strace! strace will show you a list of the syscalls being opened by your program. Passing the output through tss can show you which syscall activity is taking a lot of time, or when your program is doing a lot of stuff without going to the disk.

Caveats

If you pipe program a to program b, and program a exits with a non-zero return code, Bash will by default report a return code of zero for the entire operation. This means if you are piping output to tss or ts you may accidentally change a failing program to a passing one. Use set -o pipefail in Bash scripts to ensure that Bash will return a non-zero return code if any part of a pipe operation fails. Or add this to a Makefile:

SHELL = /bin/bash -o pipefail

Second, the program being profiled may not flush output to stdout, that is, it may print something but it may not appear on the screen at the same time it was printed. If the timings on screen don't seem to match up with your intuition, check that the program is flushing print statements to the stdout file descriptor after printing them.

Liked what you read? I am available for hire.
Where is everyone going to live?

In the middle of a housing crisis, cities up and down the Peninsula are moving forward with plans to add a ton of new office space and no new housing. These plans will add many more new commuters, without any corresponding housing for them.

  • Last year the Apple Park launched in Cupertino. 2.8 million sq ft of office space (room for 18,000 workers), no new housing.

  • Brisbane just put a plan for the Baylands on the 2018 ballot. 4 million sq ft of office space (room for 26,000 workers), 2200 housing units.

  • South San Francisco is moving forward with Oyster Point development. 1.5 million sq ft of office space (room for 10,000 workers), 1200 housing units.

  • San Francisco is moving forward with the Central SOMA Plan. 6 million sq ft of office space (room for 40,000 workers), only 7000 housing units.

  • Facebook wants to add 35,000 employees in Menlo Park, with only 1500 housing units to match.

Where are all of those commuters supposed to live? No one is planning on adding housing to match the new office space being added.

We have seen this story play out already. Those rich new workers are going to want apartments near their offices, so they'll bid up the price of existing housing. This will lead to gentrification and displacement. Everyone who can't afford to do that will commute from Pleasanton, Gilroy and Stockton. This will clog 101 and the San Mateo Bridge, leading to even worse traffic.

It cracks me up when folks say "Why doesn't Google just build their next office in Bakersfield?" Your own City Councils are rolling out the red carpet to host their next office, so they can get that sweet revenue, and don't care/don't want to add any housing to match. This is what "local control" has gotten us and the results have been ruinous.

My brother and sister have already left the Bay Area. My best friend grew up 300 yards from me and now is raising his family in Savannah, GA. I'm worried I'm going to be next. All of these new developments are the world's slowest moving steamroller, driving up rent and housing prices. $3m for a home and $4,000 median rents are in our near future.

How can we turn these traffic and displacement bombs around?

  • Call your Senator and Assemblymember to support SB 827, which could actually add enough new housing near transit to reverse our traffic problems and slow the explosive growth of rents.

  • Support new housing in your town. The State is adding bonuses for adding new housing units, but developers are choosing not to use them, for fear of community backlash. Tonight, for example, there's a meeting about 935 homes at Concar Drive at San Mateo City Hall at 7pm, and another at Millbrae City Hall about the Serra Station project adjacent to Millbrae BART. These could use voices in support.

  • If you're someone who does not benefit from a fixed rate mortgage and Prop 13, or if you are and you're worried about where your kids are going to live, consider running for City Council or applying for Planning Commission in your town. Sign up for mailing lists to get notified about new events happening: I run one (kev@inburke.com) or yimbyaction.org/sanmateo.

Liked what you read? I am available for hire.

How to write Go middleware

Writing middleware in Go seems pretty easy at first, but there are several easy ways to trip up. Let's walk through some examples.

Reading the Request

All of the middlewares in our examples will accept an http.Handler as an argument, and return an http.Handler. This makes it easy to chain middlewares. The basic pattern for all of our middlewares will be something like this:

func X(h http.Handler) http.Handler {
    return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
        // Something here...
        h.ServeHTTP(w, r)
    })
}

Let's say we want to redirect all requests with a trailing slash - say, /messages/, to their non-trailing-slash equivalent, say /messages. We could write something like this:

func TrailingSlashRedirect(h http.Handler) http.Handler {
	return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
		if r.URL.Path != "/" && r.URL.Path[len(r.URL.Path)-1] == '/' {
			http.Redirect(w, r, r.URL.Path[:len(r.URL.Path)-1], http.StatusMovedPermanently)
			return
		}
		h.ServeHTTP(w, r)
	})
}

Easy enough.

Modifying the Request

Let's say we want to add a header to the request, or otherwise modify it. The docs for a http.Handler say:

Except for reading the body, handlers should not modify the provided Request.

The Go standard library copies http.Request objects before passing them down the response chain, and we should as well. Let's say we want to set a Request-Id header on every request, for internal tracing. Create a shallow copy of the *Request and modify the header before proxying.

func RequestID(h http.Handler) http.Handler {
	return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
		r2 := new(http.Request)
		*r2 = *r
		r2.Header.Set("X-Request-Id", uuid.NewV4().String())
		h.ServeHTTP(w, r2)
	})
}

Writing Response Headers

If you want to set response headers, you can just write them and then proxy the request.

func Server(h http.Handler, servername string) http.Handler {
	return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
		w.Header().Set("Server", servername)
		h.ServeHTTP(w, r)
	})
}

Last Write Wins

The problem with the above is if the inner Handler also sets the Server header, your header will get overwritten. This can be problematic if you do not want to expose the Server header for internal software, or if you want to strip headers before sending a response to the client.

To do this, we have to implement the ResponseWriter interface ourselves. Most of the time we'll just proxy through to the underlying ResponseWriter, but if the user tries to write a response we'll sneak in and add our header.

type serverWriter struct {
	w            http.ResponseWriter
	name         string
	wroteHeaders bool
}

func (s *serverWriter) Header() http.Header {
	return s.w.Header()
}

func (s *serverWriter) WriteHeader(code int) http.Header {
	if s.wroteHeader == false {
		s.w.Header().Set("Server", s.name)
		s.wroteHeader = true
	}
	s.w.WriteHeader(code)
}

func (s *serverWriter) Write(b []byte) (int, error) {
	if s.wroteHeader == false {
		// We hit this case if user never calls WriteHeader (default 200)
		s.w.Header().Set("Server", s.name)
		s.wroteHeader = true
	}
	return s.w.Write(b)
}

To use this in our middleware, we'd write:

func Server(h http.Handler, servername string) http.Handler {
	return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
		sw := &serverWriter{
			w:    w,
			name: servername,
		}
		h.ServeHTTP(sw, r)
	})
}

What if user never calls Write or WriteHeader?

If the user doesn't call Write or WriteHeader - for example, a 200 with an empty body, or a response to an OPTIONS request - neither of our intercept functions will run. So we should add one more check after the ServeHTTP call for that case.

func Server(h http.Handler, servername string) http.Handler {
	return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
		sw := &serverWriter{
			w:    w,
			name: servername,
		}
		h.ServeHTTP(sw, r)
		if sw.wroteHeaders == false {
			s.w.Header().Set("Server", s.name)
			s.wroteHeader = true
		}
	})
}

Other ResponseWriter interfaces

The ResponseWriter interface is only required to have three methods. But in practice, it can respond to other interfaces as well, for example http.Pusher. Your middleware might accidentally disable HTTP/2 support, which would not be good.

// Push implements the http.Pusher interface.
func (s *serverWriter) Push(target string, opts *http.PushOptions) error {
	if pusher, ok := s.w.(http.Pusher); ok {
		return pusher.Push(target, opts)
	}
	return http.ErrNotSupported
}

// Flush implements the http.Flusher interface.
func (s *serverWriter) Flush() {
	f, ok := s.w.(http.Flusher)
	if ok {
		f.Flush()
	}
}

That's it

Best of luck! What middlewares have you written, and how did it go?

Liked what you read? I am available for hire.

Historically Significant Laundromats

On Tuesday, the SF Board of Supervisors moved to study whether a Mission laundromat is a historic resource, delaying 75 units of housing by 5 months. We wanted to look back at famous laundromats of history.

Garden of Eden, 6000 BC

Eating the forbidden fruit without any napkins makes quite a mess. Adam and Eve stop by the Garden of Eden Wash & Fold on their way to getting expelled from the Garden.

Mesopotamia, 1754 BC

After someone takes his clothes out of the dryer and drops them on the ground, the sixth Babylonian King, Hammurabi, has had enough. He writes a set of laws on a stone stele. The resulting Code of Hammurabi is one of the oldest deciphered writings of significant length in the world.

Wittenberg, Germany, 1517

Martin Luther posts his famous 95 Theses on the door of All Saints Church. The theses include theologically thorny questions such as "How come 60 minutes isn't ever enough time to get my clothes dry" and "Could God make a shirt so stained that even He couldn't get it clean?" Luther's questions kickstarted the Reformation, a schism that permanently divided the Catholic Church and altered Europe forever.

Easter Island, 1600

Two islanders begin arguing after one claims the other stole a pair of stonewashed jeans out of the washer at the Rapa Nui Super Wash. The ensuing fight engulfs the island. Everyone dies. The island lies empty for centuries.

Appomattox, 1865

It turns out your clothes get quite dirty during a scorched earth campaign. After accepting Lee's surrender, General Ulysses S. Grant headed to the Appomattox Soap 'n' Suds to get some clean duds.

Germany, 1867

The Trier Launderland swallows Karl Marx's quarters for the fourth straight visit. Marx publishes Das Kapital, a groundbreaking work documenting the conflict between the ruling class, which owns the means of production, and the proletariat.

Sarajevo, 1914

Gonzalo Princip doesn't realize you can't mix colors with whites and stains all his clothes. He's so mad he storms out of the Stari Grad Coin Laundry and assassinates Archduke Franz Ferdinand, starting World War I and throwing the world into turmoil.

Nadikdik Atoll, Marshall Islands

45 years after vanishing over the Pacific Ocean during her around-the-world excursion, Amelia Earhart is discovered helping the locals get clean clothes at The Clothes Spin, a punny store-name on this island of 50,000 residents.

Liked what you read? I am available for hire.

You Shouldn’t Use Faker (or other test randomization libraries)

It's a common, and distressing, pattern to have factories in tests that call out to a library like Faker to "randomize" the returned object. So you might see something like this:

User.create({
    id: uuid(),
    email: faker.random.email(),
    first_name: faker.random.firstName(),
    last_name: faker.random.lastName(),
    address: faker.random.address(),
});

package = Package.create({
    width: faker.math.range(100),
    height: faker.math.range(200),
    length: faker.math.range(300),
})

This is a bad practice and it's distressing to see it in such widespread use. I want to explain some reasons why it's bad.

The corpus is not large enough to avoid uniqueness failures

Let's say you write a test that creates two different users, and for whatever reason, the test fails if the users have the same name (due to a database constraint failure, write to same map key, array having 1 value instead of 2, &c). Faker has about three thousand different possible values for a first name. This means that every 3000th run on average, the randomly chosen names will collide, and your test will fail. In a CI environment or on a medium size team, it's easy to run the tests 3000 times in a week. Alternatively, if the same error exists in ten tests, it will emerge on average once every 300 runs.

The onus on catching failures falls on your team

Because the error only appears once in every 3000 test runs, the odds are you haven't fully or partially probed the space of possible test values when you submit your code and tests for review. This means that the other members of your team will be the ones who run into the error caused by your tests. They might lack the context necessary to effectively debug the problem. This is a very frustrating experience for your teammates.

It's hard to reproduce failures

If you don't have enough logging to see the problem on the first failure, it's going to be difficult to track down a failure that appears only once every 3,000 test runs. Run the test ten or even fifty times in a loop and it still won't appear.

An environment where tests randomly fail for unknown reasons is corrosive to build stability. It encourages people to just hit the "Rebuild" button and hope for a pass on the next try. Eventually this attitude will mask real problems with the build. If your test suite takes a long time to run (upwards of three minutes) it can be demoralizing to push the deploy or rebase button and watch your tests fail for an unrelated reason.

It's a large library (and growing)

It's common for me to write Node.js tests and have an entire test file with 50 or 100 tests exit in about 10 milliseconds.

By definition a "fixture" library needs to load a lot of fake data. In 2015 it took about 60 milliseconds to import faker. It now takes about 300 milliseconds:

var a = Date.now()
require('faker');
console.log(Date.now() - a);
$ node faker-testing/index.js
303

You can hack around this by only importing the locale you need, but I've never seen anyone do this in practice.

What you need instead

So faker is a bad idea. What should you use? It depends on your use case.

  • Unique random identifiers. If you need a random unique identifier, just use a uuid generator directly. If you create 103 trillion objects in a given test, the odds of a uuid collision are still only one in a billion, so the odds of a collision are much lower than using the faker library. Alternatively, you can use an incrementing integer each time you call your factory, so you get "Person 0", "Person 1", "Person 2", etc.

  • A fuzzer, or QuickCheck. Faker has tools for randomizing values within some input space, say a package width that varies between 0 and 100. The problem is that the default set up is to only exhaust one of those values each time you run the test, so you're barely covering the input space.

    What you really want is a fuzzer, that will generate a ton of random values within a set of parameters, and test a significant percentage of them each time the test runs. This gives a better guarantee that there are no errors. Alternatively, if there are known edge cases, you can add explicit tests for those edge cases (negative, 0, one, seven, max, or whatever). Tools like Haskell's QuickCheck or afl-fuzz make it easy to add this type of testing to your test suite.

If you want random human-looking data I suggest adding it yourself and using some scheme that makes sense for your company. For example, users named Alice and Bob are always friends that complete actions successfully, and Eve always makes errors. Riders with Android phones always want to get picked up in Golden Gate Park and taken to the Mission; riders with iPhones want to get picked up in the Tenderloin and taken to Russian Hill (or something). This scheme will provide more semantic value, and easily pinpoint errors (a "Bob" error means we should have submitted something successfully but failed to, for example).

That's all; happy testing, and may your tests never be flaky!

Liked what you read? I am available for hire.

Proxying to a subcommand with Go

There are a number of Unix commands that manipulate something about the environment or arguments in some way before starting a subcommand. For example:

  • xargs reads arguments from standard input and appends them to the end of the command.

  • chpst changes the process state before calling the resulting command.

  • envdir manipulates the process environment, loading variables from a directory, before starting a subcommand

Go is a popular language for writing tools that shell out to a subprocess, for example aws-vault or chamber, both of which have exec options for initializing environment variables and then calling your subcommand.

Unfortunately there are a number of ways that you can make mistakes when proxying to a subcommand, especially one where the end user is specifying the subcommand to run, and you can't determine anything about it ahead of time. I would like to list some of them here.

First, create the subcommand.

cmd := exec.Command("mybinary", "arg1", "-flag")
// All of our setup work will go here
if err := cmd.Run(); err != nil {
    log.Fatal(err)
}

Standard Output/Input/Error

You probably want to proxy through the subcommand's standard output and standard error to the parent terminal. Just reassign stdout/stderr to point at the parent command. Obviously, you can redirect these later.

cmd.Stdout = os.Stdout
cmd.Stderr = os.Stderr
// If you need
cmd.Stdin = os.Stdin

Environment Variables

By default the subcommand gets all of the environment variables that belong to the Go process. But if you reassign cmd.Env it will only get the variables you provide, so you have to be careful with your implementation.

cmd.Env = []string{"TZ=UTC", "MYVAR=myval"}

Signals

If someone sends a signal to the parent process, you probably want to forward it through to the child. This gets tricky because you can receive multiple signals, that all should be sent to the client and handled appropriately.

You also can't send signals until you start the process, so you need to use a goroutine to handle them. I've copied this code from aws-vault, with some modifications.

if err := cmd.Start(); err != nil {
    log.Fatal(err) // Command not found on PATH, not executable, &c.
}
// wait for the command to finish
waitCh := make(chan error, 1)
go func() {
    waitCh <- cmd.Wait()
    close(waitCh)
}()
sigChan := make(chan os.Signal, 1)
signal.Notify(sigChan)

// You need a for loop to handle multiple signals
for {
    select {
    case sig := <-sigChan:
        if err := cmd.Process.Signal(sig); err != nil {
            // Not clear how we can hit this, but probably not
            // worth terminating the child.
            log.Print("error sending signal", sig, err)
        }
    case err := <-waitCh:
        // Subprocess exited. Get the return code, if we can
        var waitStatus syscall.WaitStatus
        if exitError, ok := err.(*exec.ExitError); ok {
            waitStatus = exitError.Sys().(syscall.WaitStatus)
            os.Exit(waitStatus.ExitStatus())
        }
        if err != nil {
            log.Fatal(err)
        }
        return
    }
}

Just Use Exec

The above code block is quite complicated. If all you want to do is start a subcommand and then exit the process, you can avoid all of the above logic by calling exec. Unix has a notion of parent and children processes - when you start a process with cmd.Run, it becomes a child process. exec is a special system call that sees the child process become the parent. Consider the following program:

cmd := exec.Command("sleep", "3600")
if err := cmd.Run(); err != nil {
    log.Fatal(err)
}
fmt.Println("terminated")

If I run it, the process tree will look something like this:

 | |   \-+= 06167 kevin -zsh
 | |     \-+= 09471 kevin go-sleep-command-proxy
 | |       \--- 09472 kevin sleep 3600

If I run exec, the sleep command will replace the Go command with the sleep command. In Go, this looks something like this:

 | |   \-+= 06167 kevin -zsh
 | |     \--= 09862 kevin sleep 3600

This is really useful for us, because:

  • We don't need to proxy through signals or stdout/stderr anymore! Those are automatically handled for us.

  • The return code of the exec'd process becomes the return code of the program.

  • We don't have to use memory running the Go program.

Another reason to use exec: even if you get the proxying code perfectly right, proxying commands (as we did above) can have errors. The Go process can't handle SIGKILL, so there's a chance that someone will send SIGKILL to the Go process and then the subprocess will be "orphaned." The subprocess will be reattached to PID 1, which makes it tougher to collect.

I should note: Syscalls can vary from operating system to operating system, so you should be careful that the arguments you pass to syscall.Exec make sense for the operating system you're using. Rob Pike and Ian Lance Taylor also think it's a bad idea.

Liked what you read? I am available for hire.

Running Bazel tests on Travis CI

Bazel is a build system that was recently open sourced by Google. Bazel operates on configuration files - a WORKSPACE file for your entire project, and then per-directory BUILD.bazel files. These declare all of the dependencies for your project, using a language called Skylark. There are a number of Skylark rules for things like downloading and caching HTTP archives, and language-specific rules.

This can be a pain to set up for a new project, but the advantage is you get builds that are perfectly hermetic. In addition, if your project has a lot of artifacts, Bazel has useful tools for caching those artifacts, and builds a dependency graph that makes it easy to see when things change. For example, if you compile Javascript from Typescript, you can cache the compiled Javascript. If the Typescript source file changes, Bazel knows that only the file that changed needs to be regenerated.

Anyway there are some gotchas about running Bazel on Travis CI that I wanted to cover, and when I was looking at instructions they weren't great.

1) Install Bazel

The official instructions ask you to add the Bazel apt repository, and then install from there. You can shave a few seconds by only updating that repository, instead of all of them.

echo "deb [arch=amd64] http://storage.googleapis.com/bazel-apt stable jdk1.8" | sudo tee /etc/apt/sources.list.d/bazel.list
curl --silent https://bazel.build/bazel-release.pub.gpg | sudo apt-key add -
sudo apt-get update -o Dir::Etc::sourcelist="sources.list.d/bazel.list" \
    -o Dir::Etc::sourceparts="-" \
    -o APT::Get::List-Cleanup="0"
sudo apt-get install openjdk-8-jdk bazel

You can shave a few more seconds by just getting and installing the deb directly, though this requires you to manually update the version number when Bazel releases a new version. (This is in a Makefile, you'll need to change the syntax for Bash or a travis.yml file).

BAZEL_VERSION := "0.7.0"
BAZEL_DEB := "bazel_$(BAZEL_VERSION)_amd64.deb"

curl --silent --output /tmp/$(BAZEL_DEB) "https://storage.googleapis.com/bazel-apt/pool/jdk1.8/b/bazel/$(BAZEL_DEB)"
sudo dpkg --force-all -i /tmp/$(BAZEL_DEB)

2) Run Tests

Bazel ships with a ton of flags but these are probably the ones you want to know about/use:

  • --batch: Run in batch mode, as opposed to client-server mode.

  • --noshow_progress / --noshow_loading_progress: Travis pretends to be a TTY so it can show colors, but this causes Bazel to dump a whole bunch of progress messages to the screen. It would be nice if you could say "I can handle ANSI escape sequences relating to colors, but not screen redraws" but you only get the binary "I'm a TTY" / "I'm not", which is unfortunate. Anyway these options turn off the "show progress" log spam.

  • --test_output=errors: By default Bazel logs test failures to a log file. This option will print them to the screen instead.

  • --features: Enable features specific to a test runner. In particular for Go you may want the --features=race rule to run tests with the race detector enabled.

3) Cache Results

Bazel is much faster when it can load the intermediate results from a cache; on one library I maintain, tests run in 13 seconds (versus 47 seconds) when they are run with a full cache.

However, the Bazel caches are enormous. Caches for Go tests include the Go binary and source tree, which runs about 95MB alone. Add on other artifacts (including the Java JDK's used to run Bazel) and it's common to see over 200MB. If you are uploading or downloading caches from somewhere like S3, this can be a really slow operation. Also, it's difficult to remove large items from Bazel's cache without removing everything; the file structure makes the cache a little tough to remove parts of.

In particular, Travis's cache does go to S3, which means it skips the local caching proxies Travis sets up for e.g. apt and npm. Travis times out the cache download after 3 minutes, and Bazel quits if the cache is corrupt. In my experience Travis will not complete a 200MB cache download in 3 minutes, so your builds will fail.

That's it

For now it's probably best to eat the cold cache startup time. That's really unfortunate though; I hope we can find a better solution in the future. One way may be for Travis to run a local "remote cache", which responds to the WebDAV protocol. This would allow closer caching of Bazel objects.

It would also be nice if Travis had a "language: bazel" mode, which would come with the right version of Bazel installed for you.

Liked what you read? I am available for hire.

Make your Go Binaries Homebrew Installable

It's easier than you think to make a software package installable via Homebrew. If you depend on a very specific version of a software package (say, Postgres 9.5.3 with readline support), I highly recommend creating a Homebrew repository and publishing recipes to it. Then your team can install and update packages as easily as:

brew tap mycompany/packages
brew install mycompany/packages/postgresql

You can use the existing formulas as a jumping off point, and modify as you see fit. (Obviously this won't work for Linux folks on your team, however in my experience people running Linux in a Mac software shop have more experience building dependencies on their own).

Anyway, I wanted to describe how to install Go binaries via Homebrew. One way to do this is to compile binaries, upload them to Github releases, and install from there. However, the Homebrew core team requires that packages are buildable from the source code. (This helps check that a binary wasn't tampered with, and avoids compatibility problems with e.g. 32 bit and 64 bit systems).

If you vendor dependencies, and check in the vendor folder to Github, installation is super easy.

# Classname should match the name of the installed package.
class Hostsfile < Formula
  desc "CLI for manipulating /etc/hosts files"
  homepage "https://github.com/kevinburke/hostsfile"

  # Source code archive. Each tagged release will have one
  url "https://github.com/kevinburke/hostsfile/archive/1.2.tar.gz"
  sha256 "cc1f3c1cb505536044cbe01f44ad7da997e6a3928fac1f64590ef69d73da8acd"
  head "https://github.com/kevinburke/hostsfile"

  depends_on "go" => :build

  def install
    ENV["GOPATH"] = buildpath

    bin_path = buildpath/"src/github.com/kevinburke/hostsfile"
    # Copy all files from their current location (GOPATH root)
    # to $GOPATH/src/github.com/kevinburke/hostsfile
    bin_path.install Dir["*"]
    cd bin_path do
      # Install the compiled binary into Homebrew's `bin` - a pre-existing
      # global variable
      system "go", "build", "-o", bin/"hostsfile", "."
    end
  end

  # Homebrew requires tests.
  test do
    # "2>&1" redirects standard error to stdout. The "2" at the end means "the
    # exit code should be 2".
    assert_match "hostsfile version 1.2", shell_output("#{bin}/hostsfile version 2>&1", 2)
  end
end

Basically, download some source code, move it to $GOPATH/src/path/to/binary, build it, and put the compiled binary in $(brew --prefix)/bin.

If you don't vendor dependencies, the story gets a little more complicated because you need to download a version of all of your dependencies. Say for example I had one dependency in my project, I would add a go_resource line for each dependency, and then call stage_deps to download/install all of them in the correct places.

require "language/go"

# Classname should match the name of the installed package.
class Hostsfile < Formula
  desc "CLI for manipulating /etc/hosts files"
  homepage "https://github.com/kevinburke/hostsfile"

  # Source code archive. Each tagged release will have one
  url "https://github.com/kevinburke/hostsfile/archive/1.2.tar.gz"
  sha256 "cc1f3c1cb505536044cbe01f44ad7da997e6a3928fac1f64590ef69d73da8acd"
  head "https://github.com/kevinburke/hostsfile"

  go_resource "github.com/mattn/go-colorable" do
    url "https://github.com/mattn/go-colorable.git",
        :revision => "40e4aedc8fabf8c23e040057540867186712faa5"
  end


  depends_on "go" => :build

  def install
    ENV["GOPATH"] = buildpath


    bin_path = buildpath/"src/github.com/kevinburke/hostsfile"
    # Copy all files from their current location (GOPATH root)
    # to $GOPATH/src/github.com/kevinburke/hostsfile
    bin_path.install Dir["*"]

    # Stage dependencies. This requires the "require language/go" line above
    Language::Go.stage_deps resources, buildpath/"src"
    cd bin_path do
      # Install the compiled binary into Homebrew's `bin` - a pre-existing
      # global variable
      system "go", "build", "-o", bin/"hostsfile", "."
    end
  end

  # Homebrew requires tests.
  test do
    # "2>&1" redirects standard error to stdout. The "2" at the end means "the
    # exit code should be 2".
    assert_match "hostsfile version 1.2", shell_output("#{bin}/hostsfile version 2>&1", 2)
  end
end

And that's it! You can test your new package by creating a symlink from /usr/local/Homebrew/Library/Taps/homebrew to wherever you keep your homebrew-core checkout:

ln -s ~/code/homebrew-core /usr/local/Homebrew/Library/Taps/homebrew/homebrew-core

Then you can just use brew install commands and they'll work just as you expect.

Liked what you read? I am available for hire.

CircleCI trusts 8 analytics companies with your source code and API tokens

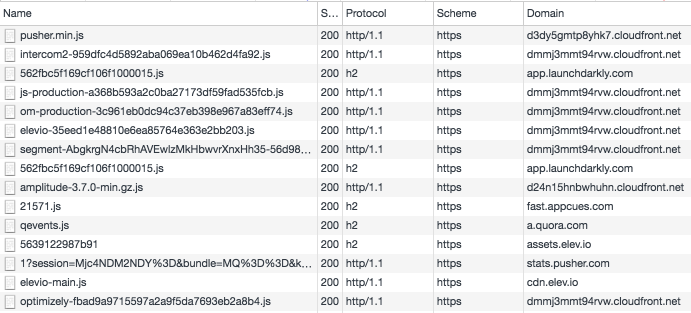
When you navigate to your project in CircleCI's UI, Javascript from eight different analytics companies gets loaded and executed in your browser.

  • Pusher
  • Intercom
  • Launch Darkly
  • Amplitude
  • Appcues
  • Quora (??)
  • elev.io
  • Optimizely

You can see this in my Network tab here:

CircleCI network requests

This is a problem because the CircleCI browser context has full access to the CircleCI API, which is hosted on the same domain, so all eight of those companies' scripts can make requests to CircleCI API endpoints. Furthermore CircleCI customers frequently either include credentials in source code or as environment variables in CircleCI. Set these, and you are trusting that CircleCI won't get compromised, or at least, your application is at most as secure as CircleCI is.

However, with eight different companies running Javascript in your browser with access to the CircleCI API, your source code and secrets are at most as secure as the union of eight different analytics companies' Javascript environments. If any of those eight gets compromised, it's trivial to execute Javascript that creates a new API token for your account. Once that token is created, an attacker can easily export it to a domain controlled by the attacker. Once an attacker has the token, they can use the "Test Commands" API to add new commands that will dump your environment variables and/or all files in source code to the logs, then download your logs or artifacts via the same API.

Analytics companies frequently get hacked, serve malware or otherwise contain vulnerabilities. Just last week it was revealed that "Code Hive" was running coin mining code on CBS's website. In 2014, jQuery.com was compromised and used to serve malware. If the same happened to any of the eight companies, you would be screwed.

This is frankly unacceptable for a company that manages source code and secrets for a large number of companies in the industry. It's unacceptable enough that your browsing data on CircleCI is potentially exposed to eight different companies, let alone API access to your source code. There are a number of steps you can take to mitigate the issue:

  • Put all domains used by the above servers in /etc/hosts, for each machine and each person on your team that accesses CircleCI. I have a tool that you can use to automate this process. However, this may break Javascript on CircleCI or other sites that are not coded in a defensive style.

  • Only use command line tools + API's to access CircleCI. I have written one such tool.

  • If there is an API to disable the "Test Commands" setting, turn it off, as an attacker can use that to put data in logs or artifacts without being able to control the circle.yml file or push to Github.

  • Don't put any sensitive keys in CircleCI, or in source code; inject them directly into the production runtime.

  • Demand that CircleCI take steps to make their dashboard and your source code more secure.

Finally, there are a number of steps CircleCI should enable immediately:

  • Don't load analytics scripts from eight different companies on pages that contain sensitive content, or that have access to the CircleCI "create token" API. Host the dashboard and API on a separate domain from the marketing page.

  • Send an email any time an API access token is created. Add a setting to allow org-wide disabling of API token creation.

  • Add an option to disable the "Test Commands" API, as this would allow an attacker without access to Github to place whatever content they want (source code/environment variables) in logs.

  • Add an option to delete old logs. If you have ever dumped env vars to the log file, an attacker can export these.

  • Enable subresource integrity, or serve JS from each of these companies from the CircleCI domain.

With embarrassing compromises literally every week, and new Congressional scrutiny into Facebook and Google's advertising practices in the 2016 election, as an industry we need to do better on issues like this.

Update: CircleCI posted their response.

Notes

Why don't you include a POC? I have one that demonstrates this attack, but I don't want to show script kiddies how. If you can't figure out how to construct it by reading the above description and the network traffic, you don't deserve to know how.

Liked what you read? I am available for hire.

Let’s talk about Javascript string encoding

Node string encoding is all over the place. Let's try to straighten out how it works.

First, some very basics about string encoding. A string is a series of bytes. A byte is 8 bits, each of which can be 0 or 1, so a byte can have 28 or 256 different values. Encoding is the process of squashing the graphics you see on screen, say, 世 - into actual bytes. There are over a million possible Unicode characters - think about all of the different languages and emoji and symbols on the planet.

You could easily represent all of the characters in the Unicode set with an encoding that says simply "assign one number, 4 bytes (or 32 bits) long, for each character in the Unicode set." One 32-bit combo for each character means you can have 4 billion distinct characters. But this would be really inefficient for most documents. For example, the English Bible or dictionary or people's email folders are mostly the characters a-z, A-Z, 0-9, and punctuation. It would be inefficient to waste 4 bytes on every "a" in the document - we want a way to represent it more efficiently.

The most common encoding is UTF-8. The main advantage of UTF-8 is that it needs a single byte (instead of four) to encode Unicode characters 0-127 - the so-called ASCII set, which includes the ones I listed above. Less common characters are represented with two bytes, and even less common characters with three bytes, and so on.

Because Javascript was invented twenty years ago in the space of ten days, it uses an encoding that uses two bytes to store each character, which translates roughly to an encoding called UCS-2, or another one called UTF-16. The letter 'a' is Unicode code point 97, so stored in a Javascript string, the first byte of a UTF-16 code point would be 97 and the second byte would be 0. The euro symbol (€) is Unicode code point 8364, so the first byte would be 172 and the second byte would be 32. (The relationship between them: 8364 = (32 << 8) + 172).

That only gets you Unicode code points 0 through (256*256 = ) 65536, though, so: if the first two-byte character is between 55296 and 56319, it's a surrogate, and you have to read the second two-byte character to figure out what Unicode code point it represents. Javascript will handle this multi-character read for you if you use the new codePointAt operator, which can return all Unicode code points, up to 1.1 million. The old charCodeAt operator only reads one character at a time (between 0 and 65536) and you'll have to read/decode the second one yourself.

Where this gets complicated

Because everything else in the world is moving to UTF-8, Node is also trying to move to UTF-8. This gets confusing because Node sometimes asks you to choose which encoding you want, in places where you wouldn't really expect it to ask.

Frequently, you want to convert from a UTF-16 encoded Javascript string to UTF-8 bytes in some form, whether a Buffer or a Uint8Array. Unfortunately Node doesn't offer easy API's to do that; it buries the conversion logic in C++ code, which eventually calls out to the V8 binary to handle it.

Buffers

Node offers a Buffer type, where a Buffer is an array of bytes, and an API, Buffer.from(string, encoding). encoding defaults to UTF-8. So far, so good! Unfortunately, sometimes encoding refers to the encoding of string, and sometimes it refers to the encoding of the bytes in the Buffer.

Buffer.from('7468697320697320612074c3a97374', 'hex') will decode the input as a series of hex characters, and store the bytes corresponding to each 2-digit hex character in the Buffer. But in var a = 'tést'; Buffer.from(a, 'utf8'); the 'utf8' refers to how the bytes will be stored in the resulting Buffer. Remember, strings are always two bytes per character, so declaring they are 'utf8' doesn't make sense.

Similarly, the encoding parameter in buf.toString(encoding) does not refer to the encoding of the output string - it refers to the encoding of the data in the buffer. Unless of course you specify hex or base64, in which case it does refer to the encoding of the output string. Got it?

HTTP

Incoming HTTP requests are often encoded using UTF-8. Node will give you data as a Buffer via the HTTP request's .on('data') event handler, which can be decoded using the content-type from the HTTP headers. In Express, this is handled in the body-parser module, which defers to the iconv-lite module for the actual encoding and decoding.

But if you expect e.g. a JSON or XML input, you will probably eventually want to turn that Buffer into a string - see the JSON section below.

When writing string data as an HTTP response, Node will wait until the last possible minute to convert that string into a Buffer that can be written to the socket. This leads to odd behaviors like the net library needing to know what encoding to use for a string you pass to it.

JSON

JSON.parse operates on a string and returns a JSON object, which may be a string or contain strings. JSON.parse and JSON.stringify don't do anything with the string encoding - if you pass in a garbage string, you get a garbage string back out.

So you need to depend on something else to determine the character encoding, before you pass a string to JSON.parse. Usually this will be your HTTP middleware; you have to trust (or verify) that it handles character sets correctly, before creating UTF-8 strings.

Files on disk

Node source files are expected to be encoded with UTF-8. That means you can encode UTF-8 source characters in a string, like this:

var x = "¢"

Where the cent character is the UTF-8 encoded byte sequence "\xc2\xa2". When Node starts and you try to reference x in your program, it will be re-encoded as a UTF-16 string. If you type the literal characters:

var x = "\xc2\xa2";

This will be turned into the UTF-16 string "\xc2\x00\xa2\x00". So be careful to mind your inputs and outputs.

Conclusion

Encoding in Node is extremely confusing, and difficult to get right. It helps, though, when you realize that Javascript string types will always be encoded as UTF-16, and most of the other places strings in RAM interact with sockets, files, or byte arrays, the string gets re-encoded as UTF-8.

This is all massively inefficient, of course. Most strings are representable as UTF-8, and using two bytes to represent their characters means you are using more memory than you need to, as well as paying an O(n) tax to re-encode the string any time you encounter a HTTP or filesystem boundary.

There's nothing stopping us from packing UTF-8 bytes into a UTF-16 string: to use each of the two bytes to store one UTF-8 character. We would need custom encoders and decoders, but it's possible. And it would avoid the need to re-encode the string at any system boundary.

Liked what you read? I am available for hire.