Author Archives: kevin

About kevin

I write the posts

Levelers

I read a great blog post in college, and sadly I can't find it now, so I'll summarize. It showed a picture of Hearst Castle, and a photo of an average middle-class home, and the text of the post went something like:

  • One of these can travel across the country in 6 hours.

  • One of these can communicate with friends and family on the other side of the country instantaneously.

  • One of these can receive news from the other side of the globe instantaneously.

  • One of these can watch movies in full color and sound in their own home.

  • One of these can expect to live to age 80, and give birth to a child without serious risk of complications.

  • One of these can wash an entire day's worth of dishes in 40 minutes with no human effort.
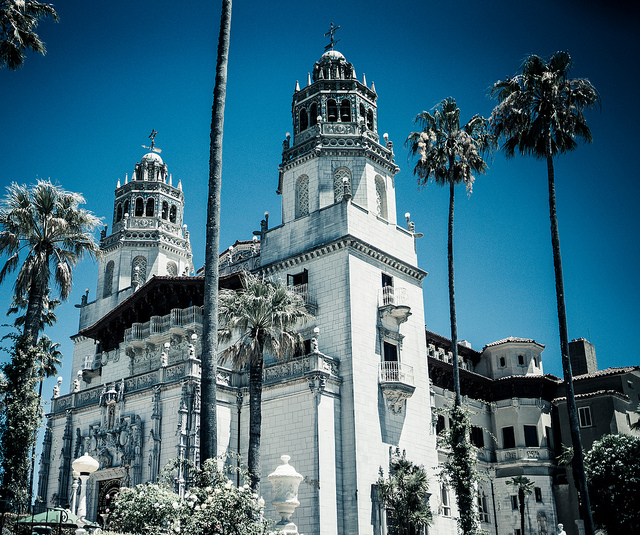
Hearst Castle. Photo credit Beedie Savage. Creative Commons BY-NC 2.0

The point is, even though Hearst was one of the richest men on the planet, in many ways the average middle class person today enjoys a better quality of life, due to advancements in technology and medical science since the 1940's.

It's really exciting when technologies (air travel, the Internet, smartphones, appliances) become accessible and cheap enough that everyone can enjoy them. But it's even more exciting when the high end of the market comes within reach of most people.

Let's say Bill Gates wants a better smartphone - say, with a longer battery, or with a UI that does exactly what he wants. He's basically out of luck - he can't throw enough money at the problem to get a better phone than what's currently on the market. A phone you can afford is the best one that Bill Gates can buy. I call products like these levelers, because they level the playing field for everyone. It's easy to think of other examples - most software/apps/websites, beers, movies, and more.

So I got excited yesterday when I read about a product that might level the playing field for another experience that's currently only for rich people.

To get a sense of what JauntVR has built, their technology is described as “an end-to-end solution for creating cinematic VR experiences.” Their camera films real world footage from everything surrounding it, and their software stitches those clips together to create a seamless experience. The wrap-around film capture means that you’re able to swivel in any direction to maintain that feeling of “actually being there.”

Rarely is the window into the future as stunningly clear as was for me for the next few minutes inside that Oculus Rift. So what was it like inside? (Keep in mind: writing about the mindshock of live action VR, is quite like trying to share a photograph of your favorite song. Words simply cannot do justice.)

I settled into a swivel chair at the center of a dark surround-sound equipped room, slid on the Rift, and instantly I was no longer in Palo Alto but sitting inches away from a string quartet performing inside a luxurious concert hall. Stunned by the realism (it is real after all!) I began turning in every direction, to discover that behind me I could see the full venue where an audience would sit. Then I understood where I was – right where the conductor would stand. Not a bad seat and with the surround sound so clear, I felt as if I was actually there.

Just like that - millions of people can suddenly all sit courtside for the NBA Finals, or even hover above the court, and suddenly, my view of the game isn't from section 400, it's as good as Jack Nicholson's.

This got me really excited for the future of virtual reality, and the new things that people are going to build on top of it. I can't wait to see what people build.

Liked what you read? I am available for hire.

Storing Photos for the Long Term

You have photos on your computer. You would probably be really sad if you lost them. Let's discuss some strategies for ensuring that doesn't happen.

What you are doing now is probably not enough.

Your current strategy is to have photos and critical files stored on your most current laptop and maybe some things in Dropbox. This means you will probably lose your data sometime in the next three years.

Hard drives fail, often, and are unrecoverable, or expensive to recover.

The software that manages your photos is written by people who are bad at their jobs, or didn't anticipate the software running on (insert hardware/software condition 10 years from now here) and it breaks, destroying your photos in the process.

Backup services fail, often enough to make you worry. Apple can't be trusted to reliably deliver messages with iMessage, I don't trust Time Machine at all.

Apartments and cars get broken into and laptops/external drives are good candidates for theft. You can buy renters insurance, but you can't get your photos back.

What you should do

I'm going to focus specifically on keeping photos for a long time. For files and folders which change more often, I use git and source code tools like Github or Bitbucket. For work environments that take a while to set up, I try to automate installation with shell scripts instead of trying to store the entire environment via Time Machine or similar.

I'm also going to pick a thirty year time horizon, just for fun. If you want something to last for thirty years, you can't just store it on your local machine because your hard drive will probably fail between now and then, and then you lose your photos. So you want to store it on your machine and then also somewhere offsite (e.g. not in the same 5-mile radius as your machine).

Storage Tool

Which raises the question, which storage/backup companies will be around in 30 years? Any small enough candidate, even Dropbox, could get acquired or shut down in that time frame. My guess right now is that Amazon Web Services will be around the longest, because it is profitable, already part of a large, growing company, and the service is growing rapidly.

Specifically, I am putting a bet on Amazon Glacier, which has extremely low storage costs - $0.01 per GB - and is one of the most reliable services Amazon runs. Glacier is a subset of Simple Storage Service (S3) which has had extraordinarily good availability in the 7-8 years it's been available. In addition Amazon regularly publishes information on the technology underpinning S3, see "Amazon Dynamo paper" for example.

I use Arq to back up photos to Glacier. It seems fairly stable, has software preferences for the right things, and I am encouraged that the author charges for the software, which means he/she has an incentive to continue developing the product and making sure that it works. This is $30 but this is still much, much cheaper than any other tool (iCloud for example would be $100 per year).

I have 52 GB of files, which means I'll pay roughly $7 per year to have 11 years of photos stored safely in the cloud. Not bad.

I would consider Tarsnap as well, which encrypts your data, but it's currently 2.5x the price of Glacier. I expect this price to decline soon.

Photo Management Software

The second piece is you need to choose a stable piece of software for viewing and managing your photos. This is orders of magnitude more risky than Glacier. The ideal piece of software would have:

  • An easy to understand file format, published online

  • Source code available online

  • Some support for grouping photos into albums and importing them from my phone/camera/whatever

  • Some sort of tool for auto-adjusting the layers on a photo, cropping it, editing the brightness/contrast. Not Lightroom, but enough to make a photo better than it was.

  • Supports hundreds of gigabytes of photos without falling over.

I haven't done as much research into this as with backup solutions, but there are a few tools. Picasa is supported by Google and relies on Google's charity to stay running and supported. Lightroom is very nice, but overshoots my needs, is very expensive, and Adobe may run out of money and fold within the next 30 years. This leaves iPhoto, which isn't well documented, or open source, but mostly works, some of the time, can crop/edit photos while saving the originals, and is a core component of Apple's Mac product, which may also die, when we all have tablets. At least iPhoto stores the files on disk.

If I was a better person, I'd manually arrange photos in files on my filesystem and use that. But I am not.

Problems

In this game it's a question of how paranoid you want to be, and how much your photos are worth to you. If they're worth a lot it's worth investing significant time and resources into redundant backup systems. Specifically, the 3-2-1 rule suggests storing backups in 3 different places, 2 different file systems (or photo management tools), with at least one offsite. For photos, backing up to CD's or tapes is not a terrible option though it's not very efficient and CD's also die. Using a 2nd photo management software solution, storing the data for that one on an external drive, and backing one of them up to Glacier every night is not a terrible idea.

My photos are worth a lot to me, but I'm not going to go insanely overboard; if my hard drive dies, and Glacier loses my data, that would suck, but I'm willing to gamble on the one-in-a-million odds of them not both happening simultaneously.

I am most worried about the management software; recently iPhoto decided I had no photos in my library and deleted all of the metadata for those photos (albums, rotation information, etc), leaving only the raw copies in my library. This was very sad, though I didn't lose the photos themselves, and might be able to recover the metadata if I am lucky. So yeah, I am not too happy with this. I now store important iPhoto databases in git, backed up to Bitbucket, so I can pull them back down in the event of another catastrophic failure.

Conclusion

This is too long already. Ensuring your photos aren't lost is difficult, and probably requires professional experience as a computer programmer to get right, or for you to part with a significant amount of money, or achieve a large amount of good luck, to avoid the bad things that happen to most people who just hope their photos stick around. I wish you the best of luck.

Liked what you read? I am available for hire.

Figure out when long-running jobs finish, without stopping them

You kick off a long running job - maybe a data migration script that operates on a large data set, or you're copying a large file from one disk to another, or from the Internet to your local computer.

Then a few minutes in, you realize the job is going to take longer than you thought, and you'd like to trigger some action when it's done - notify you, or remove a temp directory, or something.

Like this: wget reallybigfile.com/bigfile.mp3 && say "file done downloading"

But you can't queue an action without hitting Ctrl+C and restarting the job, setting you back minutes or hours. Or can you?

With most modern shells on Unix, you can suspend the running process, and the Unix machine will freeze the state of the process for you. Simply hit Ctrl+Z while any process is running and you will get a message like this:

$ sleep 10
^Z
[1]  + 72277 suspended  sleep 10

You can then resume it with the fg command, which tells Unix to resume operations with the suspended process. You can then combine fg with the notification command of your choice. So let's say you've suspended the process with Ctrl+Z, you can bring it back to the foreground and attach actions afterwards like so:

fg; say -vzarvox "Job complete."

Of course, you can do whatever you want instead of using the say command; trigger another long running operation or whatever.

I use this probably about once a day, it never fails and it's always useful. Hope it helps you too!

Liked what you read? I am available for hire.

Easy maintenance of your AUTHORS file

It's important to recognize the people that have contributed to your project, but it can be annoying to keep your project's AUTHORS file up to date, and annoying to ask everyone to add themselves in the correct format.

So I did what any good engineer should do, and automated the process! I added a simple make target that will update the authors file based on the current Git history:

    # Run this command to update AUTHORS.md with the latest contributors.
    authors:
        echo "Authors\n=======\nWe'd like to thank the following people for their contributions.\n\n" > AUTHORS.md
        git log --raw | grep "^Author: " | sort | uniq | cut -d ' ' -f2- | sed 's/^/- /' >> AUTHORS.md

Essentially, that snippet gets every author from the git history, sorts and unique-ifies the list, strips the word "Author: " from the line, and outputs the new list to the AUTHORS.md file. Now updating the authors list is as easy as running make authors from the command line.

Liked what you read? I am available for hire.

The SSL library ecosystem needs diversity

The Heartbleed bug was really bad for OpenSSL - it let you ask a server a simple question like "How are you" and then have the server tell you anything it wants (password data, private keys that could be used to decrypt all traffic), and the server would have no idea it was happening.

A lot of people have said that we should ditch OpenSSL because this bug is so bad, and because there are parts of the codebase that are odd, and would usually indicate bad programmers, except that they are found in a library that is deployed everywhere.

Ditching OpenSSL is not going to happen any time soon because it is the standard implementation for any server that has to terminate SSL traffic, and writing good crypto libraries is very difficult. So this is not a promising approach.

However this bug and the subsequent panic (as well as the flood of emails telling me to reset passwords etc) indicate the problem with having every software company in the world rely on the same library. Imagine that there were three different SSL software tools that each had a significant share of the market. A flaw in one could affect, at most, the users of that library. Diversification reduces the value of any one exploit and makes it more difficult to find general attacks against web servers.

This diversity is what makes humans so robust against things like the Spanish Flu, which killed ~100 million people but didn't make a dent on the overall human population. Compare that with the banana, which is susceptible to a virus that could wipe out the entire stock of bananas around the world.

You can see the benefits of diversity in two places. One, even inside the OpenSSL project, users had different versions of the library installed on their servers. This meant that servers that didn't have versions 1.0.1a-f installed (like Twilio) were not vulnerable, which was good.

The second is that servers use different programming languages and different frameworks. This means that the series of Rails CVE's were very bad for Rails deployments but didn't mean anything for anyone else (another good thing).

After Heartbleed I donated $100 to the OpenSSL Foundation, in part because it is really important and in part because it's saved me from having to think about encrypting communication with clients (most of the time) which is really, really neat. I will match that donation to other SSL libraries, under these conditions:

  • The library's source code is available to the public.

  • There is evidence that the code has been used in a production environment to terminate SSL connections.

  • The project has room for more funding.

This is not a very large incentive, but it's at least a step in the right direction; if you want to join my pledge, I'll update the dollar amounts and list your name in this post. A prize of $10 million put a rocket into space; I'm hoping it will help spur diversity in the SSL ecosystem as well.

Liked what you read? I am available for hire.

Source code stolen from Github.com

The open source community was shocked to learn Tuesday that millions of lines of source code had gone missing from Github.com, a popular online version control website.

Github stores source code in "reposotories", which are big chunks of code that can be edited by Github members. Most version control websites will keep a small portion of the source code online (collectively known as the "hot repos") and store the rest of the repos offline, to prevent a mass download of all of the source code. Instead of using hot repos and cold repos, Github stored all of the source code online, which allowed the attackers to download all of it.

It's unclear how long the source code has been missing. Slides from a leaked Keynote deck indicated that Github's main strategy was to "just kinda ask people to push their code back up to the site without noticing anything". On Twitter, some people attributed the theft to an honest mistake (Github left the popular port 22 open for the attackers), while others speculated that the founders absconded with the code after building up trust in Github.

Github is based on a "distributed version control" system, designed so that many different copies of the source code can live on different computers. But because everyone stores their source code in Github, it became very easy for the attackers to download all of the source code from one place.

"My code could be running on anyone's computer right now, anywhere in the world," said open source developer Andrew Benton. "Frankly, that is terrifying." Other members of the community laughed at anyone who thought their source code was secure when hosted with a version control system that runs in the cloud.

Github could not be reached for comment, but they did release a special "Hackedocat" to commemorate the occasion.

Hackedocat!

At press time, the top comments on Hacker News were from a person complaining about how dumb Github is for losing the code, another person explaining to everyone that this article is satire, and a third person explaining that while he understands this is satire, the article is "dumb" and "not that funny", and seven non-sequiturs about the wisdom of free markets.

with thanks to Kyle Conroy, Andrew Benton, and Gabriel Gironda for reading drafts, and to Kyle for the Hackedocat

Liked what you read? I am available for hire.

Go to Hong Kong Disneyland

On a Friday in April, the lines for Space Mountain and Thunder Valley did not exceed 10 minutes all day. Astro Blasters twice had 4 people in line. The price is $60, which is ~$30 cheaper than Anaheim.

It was about 80 degrees during the day and 70 at night. Also when you exit Disneyland HK you are in Hong Kong, which is much nicer than Orange County, but maybe not for dim sum. You can take the metro from downtown and get there in under 45 minutes.

There are analogues for most rides in Disneyland, noticeable absences are Indiana Jones and Pirates of the Caribbean.

Big draws are the character shows, Winnie the Pooh, and Fantasyland, so if you’re not really interested in those you are in lots of luck.

Liked what you read? I am available for hire.

A look at the new retry behavior in urllib3

"Build software like a tank." I am not sure where I read this, but I think about it a lot, especially when writing HTTP clients. Tanks are incredible machines - they are designed to move rapidly and protect their inhabitants in any kind of terrain, against enemy gunfire, or worse.

HTTP clients often run in unfriendly territory, because they usually involve a network connection between machines. Connections can fail, packets can be dropped, the other party may respond very slowly, or with a new unknown error message, or they might even change the API from under you. All of this means writing an HTTP client like a tank is difficult. Here are some examples of things that a desirable HTTP client would do for you, that are never there by default.

  • If a request fails to reach the remote server, we would like to retry it no matter what. We don't want to wait around for the server forever though, so we want to set a timeout on the connection attempt.

  • If we send the request but the remote server doesn't respond in a timely manner, we want to retry it, but only on requests where it is safe to send the request again - so called idempotent requests.

  • If the server returns an unexpected response, we want to always retry if the server didn't do any processing - a 429, 502 or a 503 response usually indicate this - as well as all idempotent requests.

  • Generally we want to sleep between retries to allow the remote connection/server to recover, so to speak. To help prevent thundering herd problems, we usually sleep with an exponential back off.

Here's an example of how you might code this:

def resilient_request(method, uri, retries):
    while True:
        try:
            resp = requests.request(method, uri)
            if resp.status < 300:
                break
            if resp.status in [429, 502, 503]:
                retries -= 1
                if retries <= 0:
                    raise
                time.sleep(2 ** (3 - retries))
                continue
            if resp.status >= 500 and method in ['GET', 'PUT', 'DELETE']:
                retries -= 1
                if retries <= 0:
                    raise
                time.sleep(2 ** (3 - retries))
                continue
        except (ConnectionError, ConnectTimeoutError):
            retries -= 1
            if retries <= 0:
                raise
            time.sleep(2 ** (3 - retries))
        except TimeoutError:
            if method in ['GET', 'PUT', 'DELETE']:
                retries -= 1
                if retries <= 0:
                    raise
                time.sleep(2 ** (3 - retries))
                continue

Holy cyclomatic complexity, Batman! This suddenly got complex, and the control flow here is not simple to follow, reason about, or test. Better hope we caught everything, or we might end up in an infinite loop, or try to access resp when it has not been set. There are some parts of the above code that we can break into sub-methods, but you can't make the code too much more compact than it is there, since most of it is control flow. It's also a pain to write this type of code and verify its correctness; most people just try once, as this comment from the pip library illustrates. This is a shame and the reliability of services on the Internet suffers.

A better way

Andrey Petrov and I have been putting in a lot of work make it really, really easy for you to write resilient requests in Python. We pushed the complexity of the above code down into the urllib3 library, closer to the request that goes over the wire. Instead of the above, you'll be able to write this:

def retry_callable(method, response):
    """ Determine whether to retry this
    return ((response.status >= 400 and method in IDEMPOTENT_METHODS)
            or response.status in (429, 503))
retry = urllib3.util.Retry(read=3, backoff_factor=2,
                           retry_callable=retry_callable)
http = urllib3.PoolManager()
resp = http.request(method, uri, retries=retry)

You can pass a callable to the retries object to determine the retry behavior you'd like to see. Alternatively you can use the convenience method_whitelist and codes_whitelist helpers to specify which methods to retry.

retry = urllib3.util.Retry(read=3, backoff_factor=2,
                           codes_whitelist=set([429, 500]))
http = urllib3.PoolManager()
resp = http.request(method, uri, retries=retry)

And you will get out the same results as the 30 lines above. urllib3 will do all of the hard work for you to catch the conditions mentioned above, with sane (read: non-intrusive) defaults.

This is coming soon to urllib3 (and with it, to Python Requests and pip); we're looking for a bit more review on the pull request before we merge it. We hope this makes it easier for you to write high performance HTTP clients in Python, and appreciate your feedback!

Thanks to Andrey Petrov for reading a draft of this post.

Liked what you read? I am available for hire.

How to create rich links in your Sphinx documentation

This will be short, but it seems there's some difficulty doing this, so I thought I'd share.

The gist is, any time you reference a class or method in your own library, in the Python standard library, or in another third-party extension, you can provide a link directly to that project's documentation. This is pretty amazing and only requires a little bit of extra work from you. Here's how.

The Simplest Type of Link

Just create a link using the full import path of the class or attribute or method. Surround it with backticks like this:

Use :meth:`requests.Request.get` to make HTTP Get requests.

That link will show up in text as:

Use requests.Request.get to make HTTP Get requests.

There are a few different types of declarations you can use at the beginning of that phrase:

:attr:
:class:
:meth:
:exc:

The full list is here.

I Don't Want to Link the Whole Thing

To specify just the method/attribute name and not any of the modules or classes that precede it, use a squiggly, like this:

Use :meth:`~requests.Request.get` to make HTTP Get requests.

That link will show up in text as:

Use get to make HTTP Get requests.

I Want to Write My Own Text

This gets a little trickier, but still doable:

Use :meth:`the get() method <requests.Request.get>` to make HTTP Get requests.

That link will show up in text as:

Use the get() method to make HTTP Get requests.

I want to link to someone else's docs

In your docs/conf.py file, add 'sphinx.ext.intersphinx' to the end of the extensions list near the top of the file. Then, add the following anywhere in the file:

    # Add the "intersphinx" extension
    extensions = [
        'sphinx.ext.intersphinx',
    ]
    # Add mappings
    intersphinx_mapping = {
        'urllib3': ('http://urllib3.readthedocs.org/en/latest', None),
        'python': ('http://docs.python.org/3', None),
    }

You can then link to other projects' documentation and then reference it the same way you do your own projects, and Sphinx will magically make everything work.

I want to write the documentation inline in my source code and link to it

Great! I love this as well. Add the 'sphinx.ext.autodoc' extension, then write your documentation. There's a full guide to the inline syntax on the Sphinx website; confusingly, it is not listed on the autodoc page.

    # Add the "intersphinx" extension
    extensions = [
        'sphinx.ext.autodoc',
    ]

Hope that helps! Happy linking.

Liked what you read? I am available for hire.

New blog post about HAProxy

Over on the Twilio Engineering Blog, I have a new post about optimizing your HAProxy configuration. I wrote this mostly because we had some confusion in our configuration about setting options, and if I had it I figured others would as well. Here's a sample:

retries 2
option redispatch
When I said a 30 second connect timeout meant HAProxy would try a bad connection for 30 seconds, I lied. It turns out that by default HAProxy will retry the connect attempt 3 times. So our 30 second connect timeout is actually a 120 second connect timeout, blowing through our SLA and meaning we're returning an empty response to the customer.

Read the full post to learn more about HAProxy.

Liked what you read? I am available for hire.